Benchmarking Nox against ComfyUI
How we make sure Nox and ComfyUI run exactly the same job before we compare a single number, and what the outputs look like side by side.
A speedup is only meaningful if both sides did the same work. It is easy to make an inference engine look fast: run fewer steps, drop to a lower resolution, swap in a smaller or more aggressively quantized checkpoint, or compare a warm process against a cold one. We wanted the Nox benchmarks to be immune to all of that, so this post explains how the comparison is set up and then shows every output from the latest run next to its ComfyUI counterpart.
Run it yourself
The ComfyUI side of the benchmark is open source: comfyuibenchmark on GitHub. You can run it on your own GPU and check our ComfyUI numbers yourself. The harness is a small set of scripts with everything pinned: the ComfyUI commit, the Python packages, the model files and the workflow graphs.
1git clone https://github.com/SpectralStudiosBV/comfyuibenchmark
2cd comfyuibenchmark
3./install.sh
4./run.sh
The models listed in link-models.sh have to be in your Hugging Face cache first. A Docker image and a Nix shell are included. run.sh writes the cold time, warm time and peak VRAM for every pipeline to output/result.log, along with the warm outputs.
Same job, both engines
Every item below is fixed in the harness and identical between ComfyUI and Nox.
- Same ComfyUI, untouched. ComfyUI is checked out at a pinned commit (
426f5eea, version 0.43.0) and runs in a locked Python environment with PyTorch 2.9.1+cu128. No custom nodes are installed and no ComfyUI code is patched. It starts with default flags. - Same workflows. Every ComfyUI workflow is taken from ComfyUI’s official workflow templates and uses only core nodes. Only the model file names, prompt, seed, resolution and frame count were changed to the shared benchmark values. Each graph is in the repository as a plain API-format script, so you can compare it with the template in the ComfyUI frontend.
- Same checkpoints. Both engines load the exact same weight files.
- Same generation settings. The benchmark reports list the output, resolution and frame count of every pipeline. All other settings can be found in the benchmark repository.
- Same machine, same measurement. Both engines run back to back on the same GPU. Each pipeline runs twice. The first run is the Cold run and includes model loading. The second, identical apart from an incremented seed, is the Warm run. On the ComfyUI side a run is timed from the moment the workflow is queued with
POST /promptuntil/historyreports it complete. That is the time a user waits, not just the time spent in the sampler.
Checking the outputs, not just the clock
Matching settings on paper is not enough. If Nox quietly skipped work or computed something different, the timings would still look good, but the output would not. So every warm output from Nox is compared with the warm output from ComfyUI using the structural similarity index (SSIM).
SSIM compares local patterns of brightness, contrast and structure between two images and returns a score from 0 to 1. A score of 1 means the images are identical. We compute it with scikit-image on full-resolution RGB pixels:
- Images: one SSIM score over all RGB pixels of the two warm images.
- Videos: both MP4s are decoded to raw RGB frames with FFmpeg. The harness checks that both videos have the same dimensions and the same number of frames, then picks nine evenly spaced frames, from the first frame to the last. SSIM is computed for each of the nine frame pairs and the nine scores are averaged.
SSIM measures how close two outputs are, not which one is better. Diffusion models amplify tiny numerical differences. Over a handful of denoising steps a last-bit difference can grow into a visibly different image. We explain where those differences come from in The differences. A high score shows that Nox renders essentially the same image from the same inputs.
Side by side
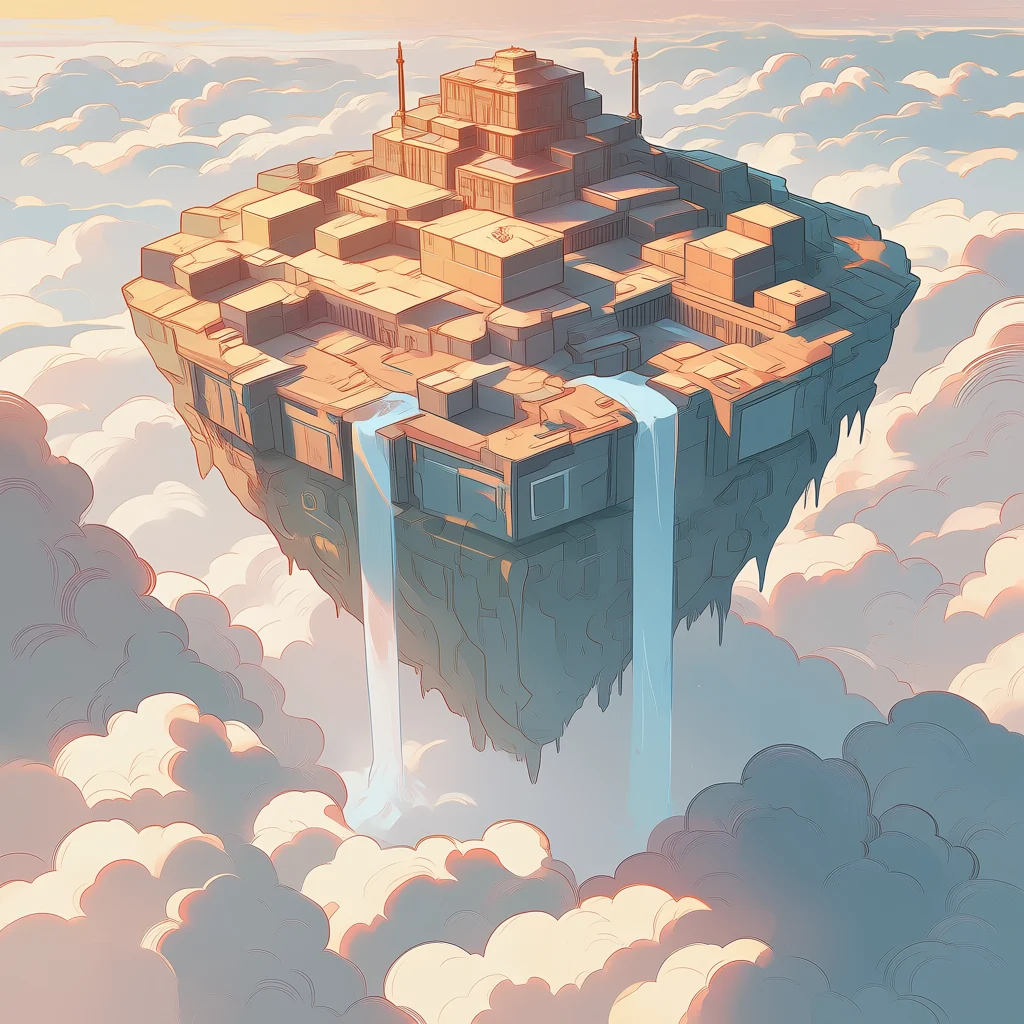
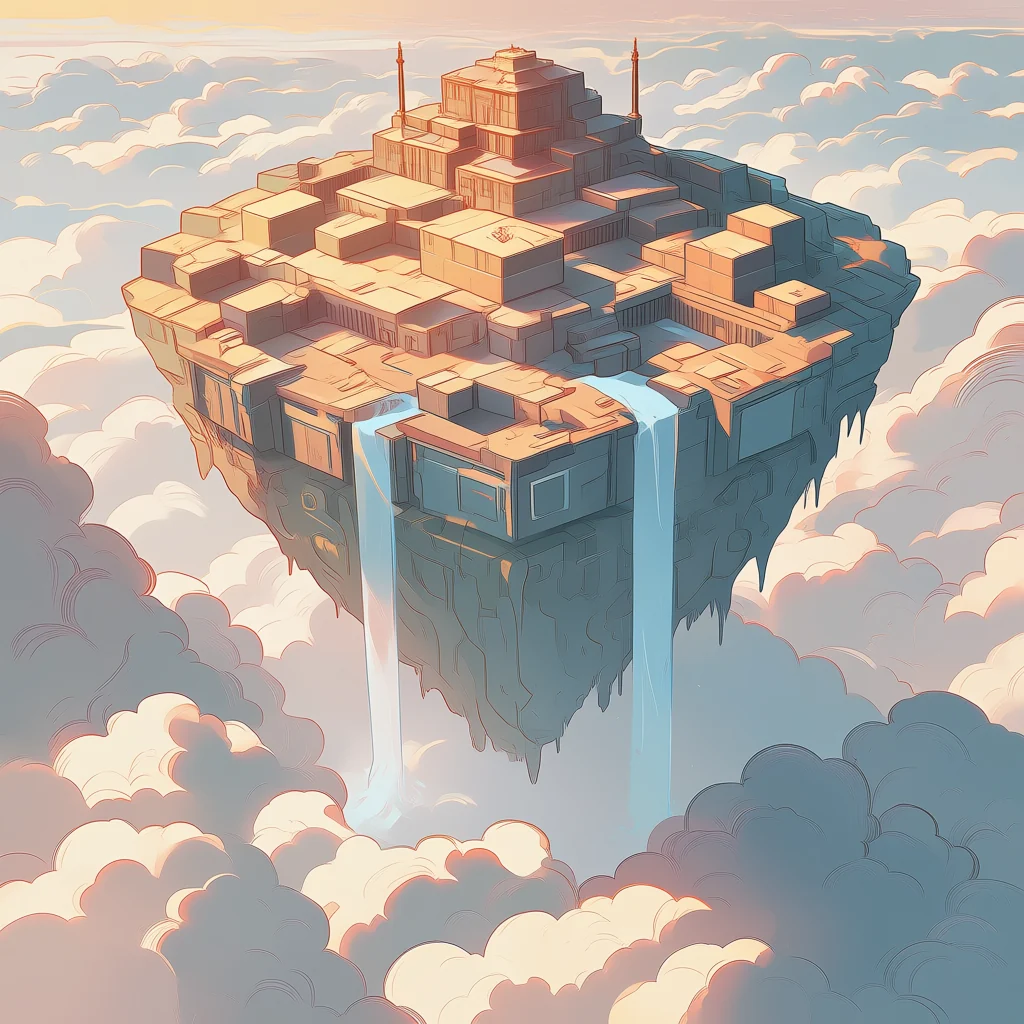
The pairs below come from our latest run, on an NVIDIA GeForce RTX 4080. The full timing tables are on the RTX 4080 benchmark page. Nox is on the left and ComfyUI is on the right. Drag the divider, or focus the slider and use the arrow keys. Videos play both outputs in sync. Pause them, step frame by frame with ‹ and ›, or drag the frame bar to compare any frame exactly.
Anima: SSIM 0.9726
FLUX.2 Klein 4B: SSIM 0.9305
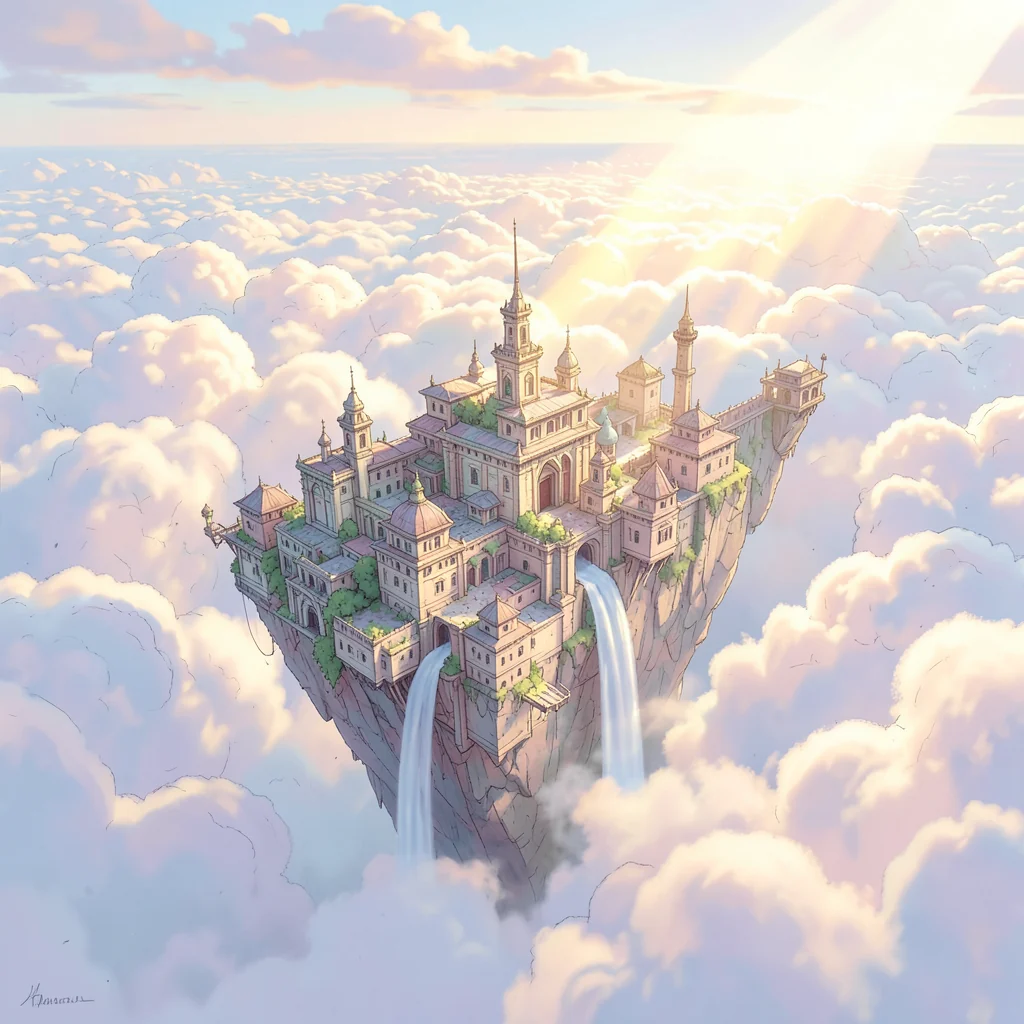
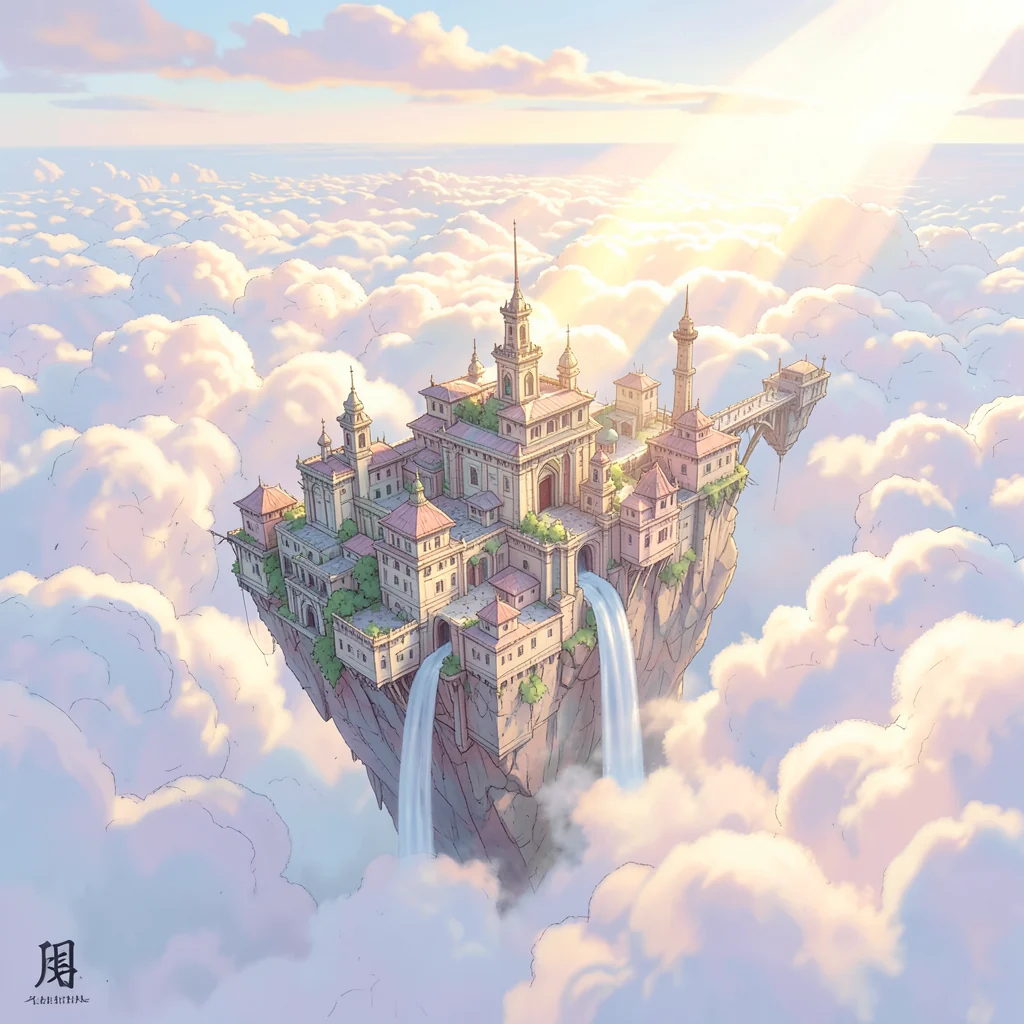
FLUX.2 Klein 9B: SSIM 0.9316
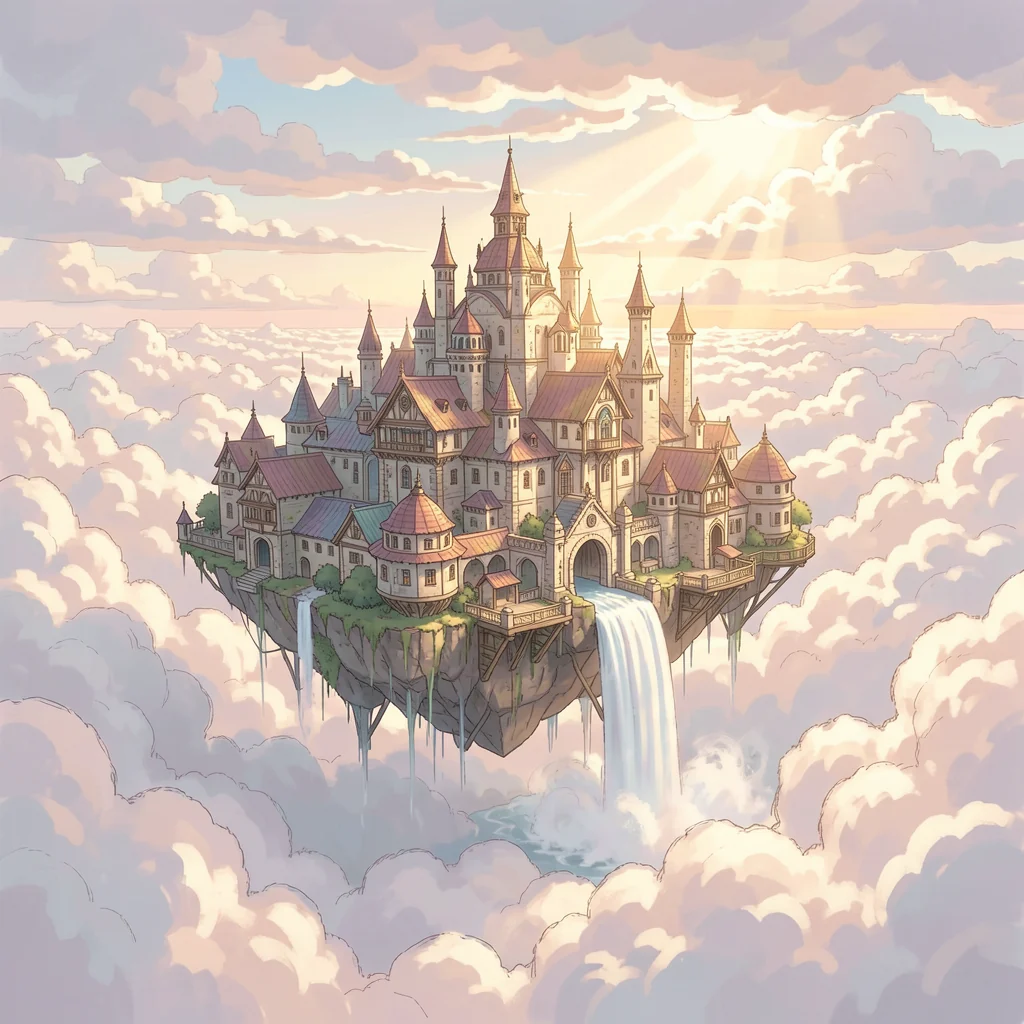
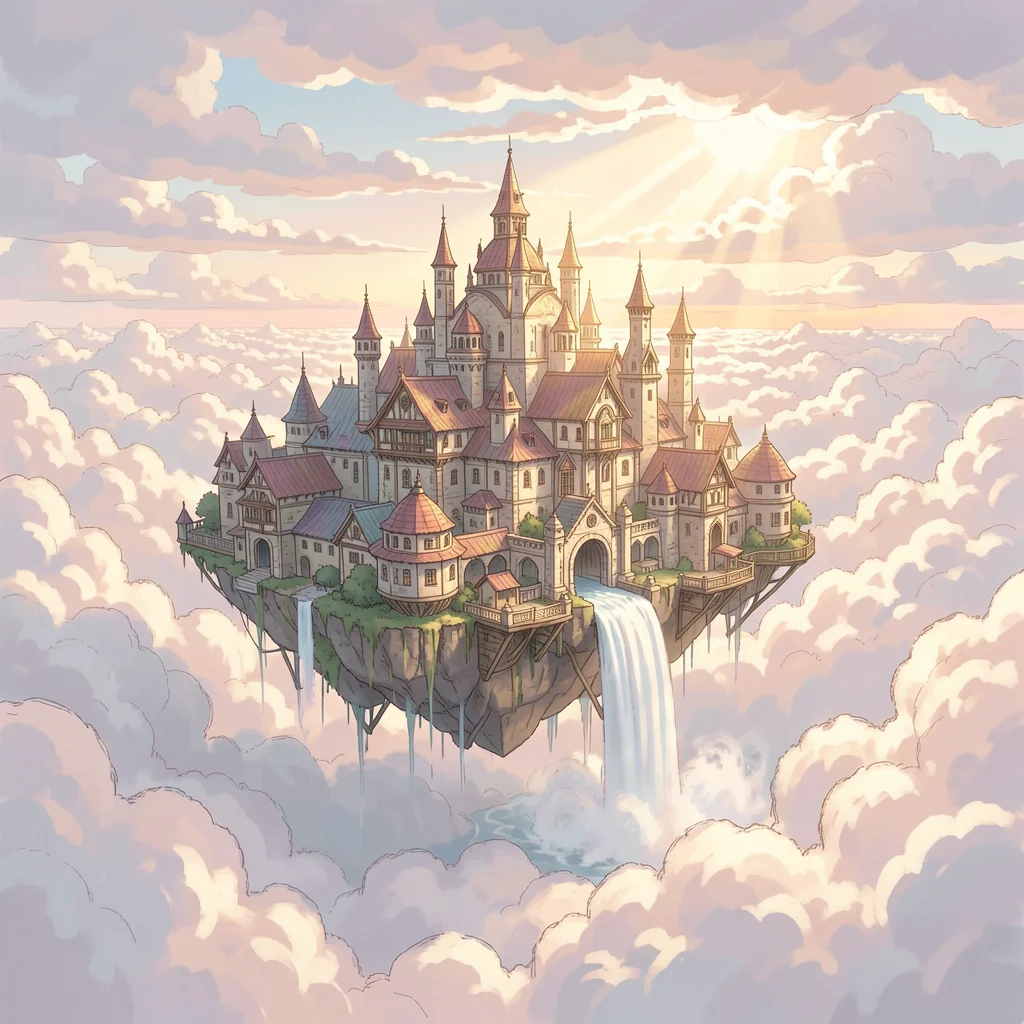
Ideogram 4: SSIM 0.8855
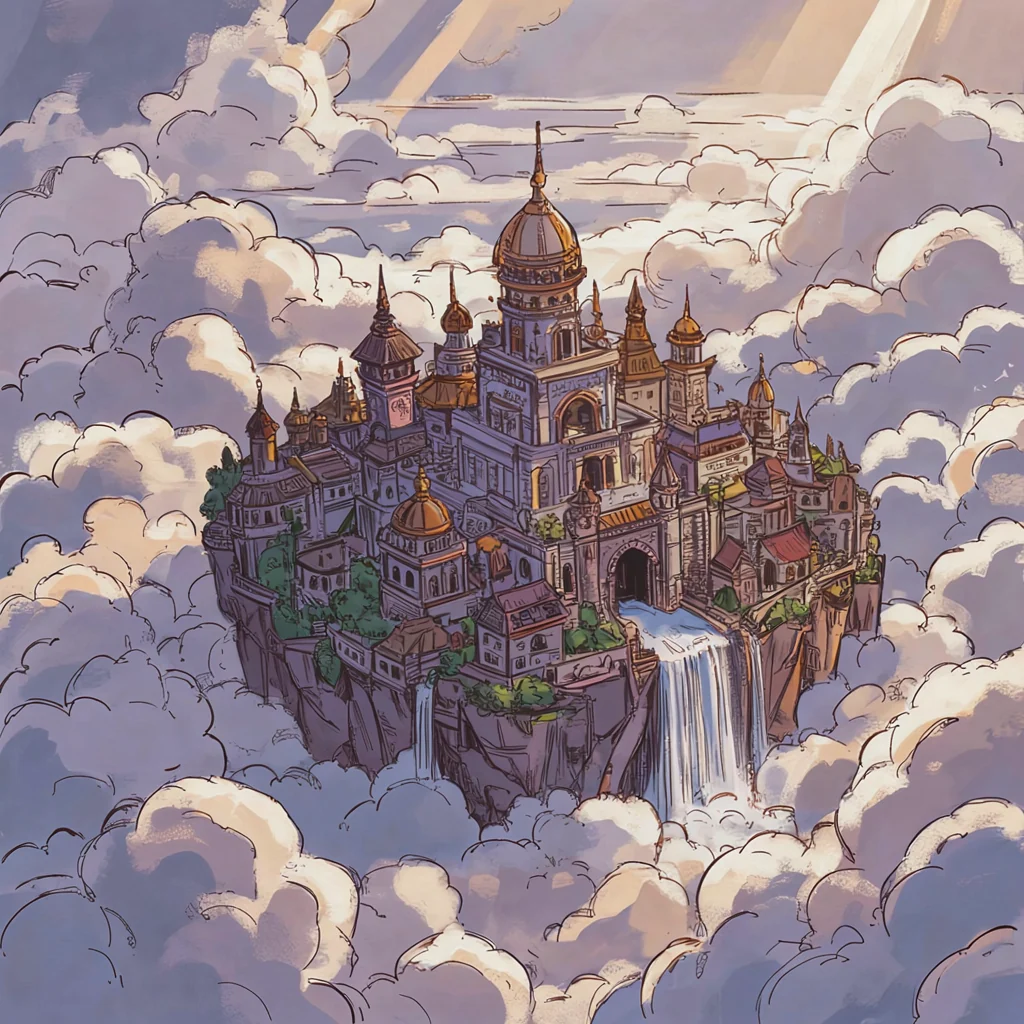
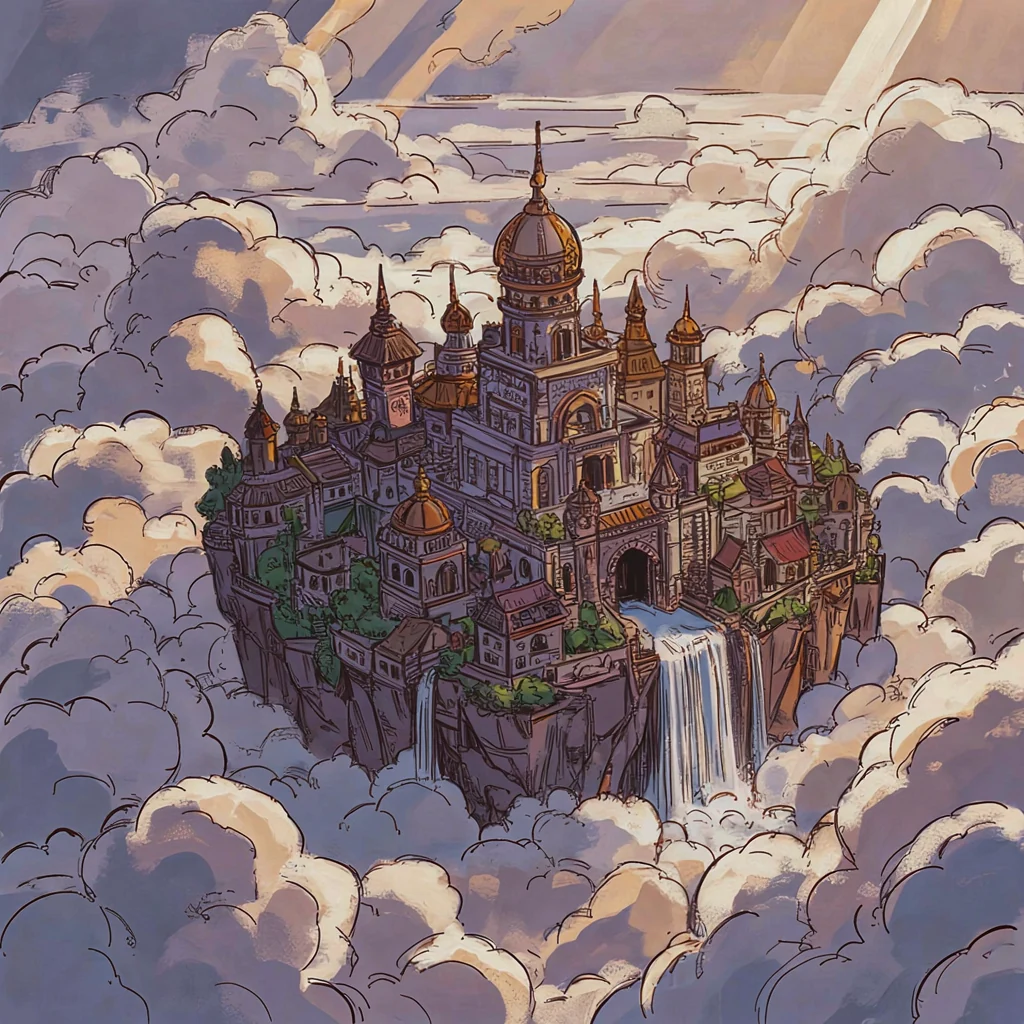
Krea 2: SSIM 0.9144
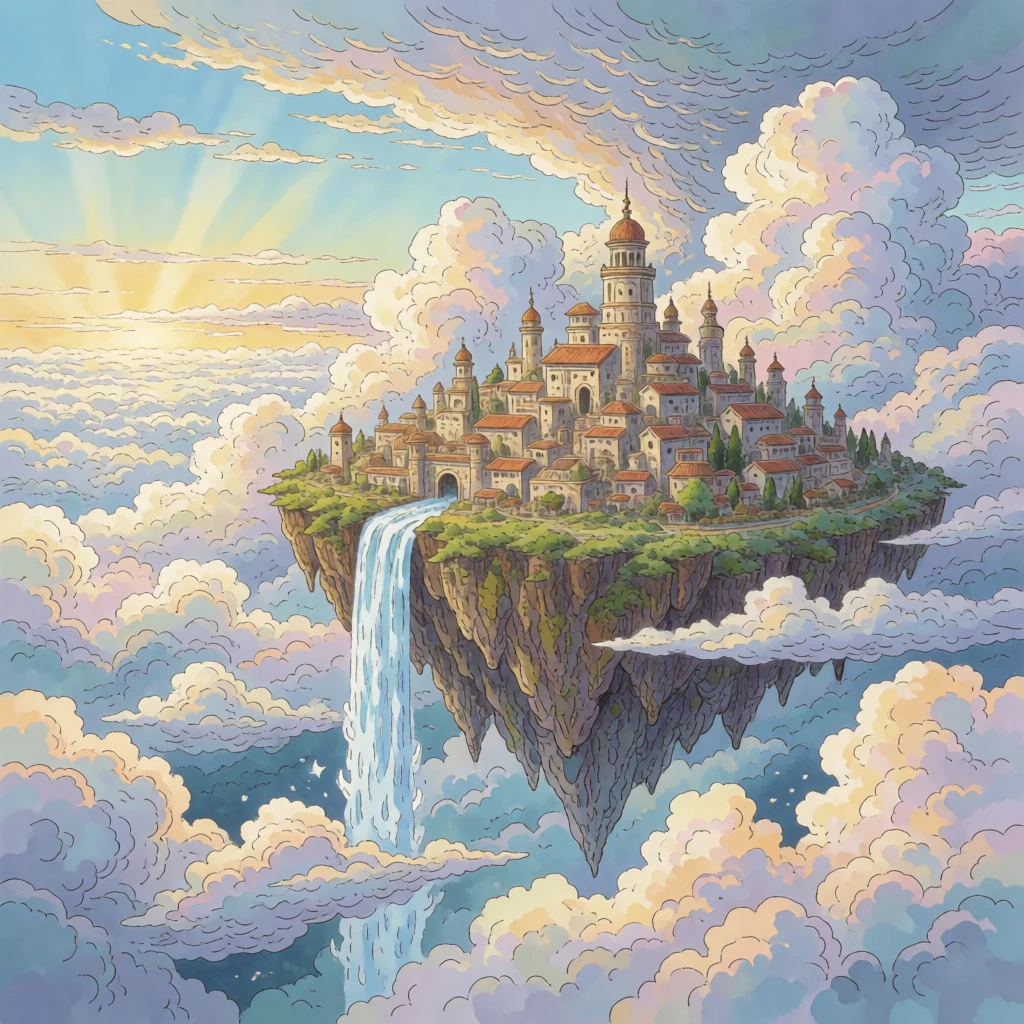
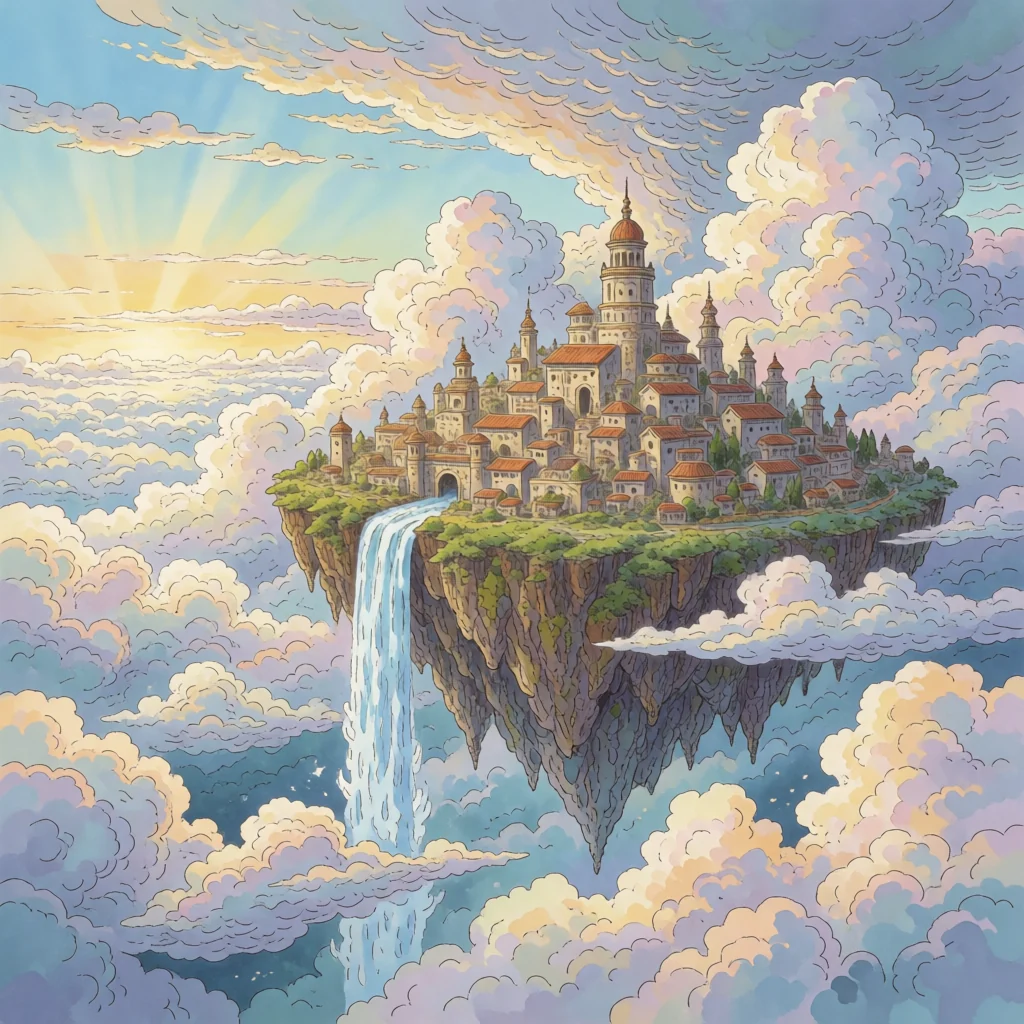
LTX-2.3 Video: SSIM 0.8562
LTX-2.5 Video: SSIM 0.9134
MiniMax-H3 Video: SSIM 0.4822
MOSS-Image: SSIM 0.9100
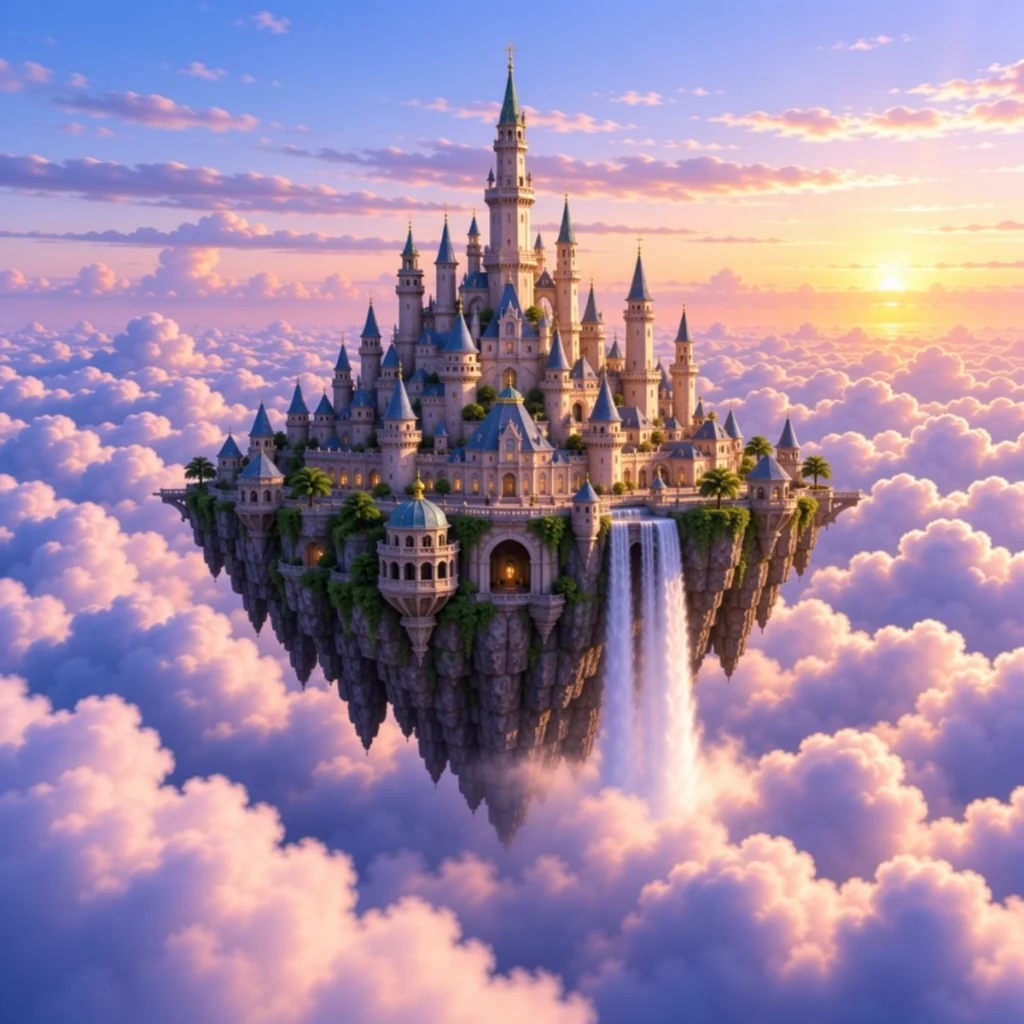
Qwen Image 2512: SSIM 0.6288
Qwen Image 2.1: SSIM 0.9898
Stable Diffusion XL: SSIM 0.9185
Z-Image: SSIM 0.9308
The similarities
A diffusion model starts from random noise, so two engines can only render the same image if they start from the same noise. Nox uses the same random number generators as ComfyUI:
- Initial noise. ComfyUI draws the starting latent on the CPU with PyTorch’s Mersenne Twister generator (mt19937). Nox implements the same generator, so both engines start from the same latent for a given seed.
- Noise during sampling. Ancestral samplers such as euler ancestral add fresh noise after every step. Both implement the same Philox generator, so the noise injected at each step matches as well.
- FP32 latent. Both engines keep the latent in FP32 between steps. The model itself runs in reduced precision on both sides, but the state carried from one step to the next is not rounded down in between.
With the same starting point, the same noise at every step and the same precision between steps, any remaining difference comes from inside the model.
The differences
Inside the model, both engines compute the same operations on the same weights, apart from how LoRAs are applied (see below), but not always in the same order. Floating point arithmetic is not associative: adding the same numbers in a different order can change the last bits of the result. A few places where the order differs between the two engines:
- Attention kernels. Attention sums over thousands of tokens. Different kernels split that sum differently across GPU threads and combine the partial results in a different order.
- Matrix multiplication. The INT8 multiplication itself is exact, but converting the result back to floating point, scaling it and adding the bias can happen in a different order or precision depending on the kernel.
- Combined operations. An engine can fuse several steps into one kernel.
Each of these changes only the last bits of a value, but diffusion amplifies small differences over the denoising steps.
What a good score looks like
A score on its own doesn’t say much: how high two valid renders can score depends on the model. To calibrate the scores, we ran every pipeline in ComfyUI twice more and compared each result with ComfyUI’s own benchmark output:
- Attention kernel swapped. Same workflow and seed, but ComfyUI is started with
--use-split-cross-attention. This replaces PyTorch’s SDPA attention with ComfyUI’s own split attention. The math is the same, only the order of the floating point operations changes, so this shows how close two equally correct renders get. It’s the score to match. - Different seed. Same workflow, seed 44 instead of 43. This produces a different but equally plausible image of the same prompt. It shows how much SSIM the shared prompt and style give you for free, the floor.
| Pipeline | Nox vs ComfyUI | ComfyUI, attention swapped | ComfyUI, different seed |
|---|---|---|---|
| Anima | 0.9726 | 0.9556 | 0.51 |
| FLUX.2 Klein 4B | 0.9305 | 0.9842 | 0.62 |
| FLUX.2 Klein 9B | 0.9316 | 0.9488 | 0.56 |
| Ideogram 4 | 0.8855 | 0.9097 | 0.26 |
| Krea 2 | 0.9144 | 0.8984 | 0.37 |
| LTX-2.3 Video | 0.8562 | 0.8610 | 0.55 |
| LTX-2.5 Video | 0.9134 | 0.8929 | 0.45 |
| MiniMax-H3 Video | 0.4822 | 0.6566 | 0.40 |
| MOSS-Image | 0.9100 | 0.9007 | 0.52 |
| Qwen Image 2512 | 0.6288 | 0.9204 | 0.47 |
| Qwen Image 2.1 | 0.9898 | 0.8920 | 0.55 |
| Stable Diffusion XL | 0.9185 | 0.9473 | 0.43 |
| Z-Image | 0.9308 | 0.9196 | 0.56 |
For 11 of the 13 pipelines, Nox is about as close to ComfyUI as ComfyUI is to itself with a different attention kernel. All 11 are far above the different-seed floor.
Running the benchmark workflow again in ComfyUI without changes reproduces its output almost exactly, with an SSIM of 0.96 or higher for every pipeline. Even the reference isn’t always bit-for-bit reproducible.
The two clear exceptions, MiniMax-H3 at 0.48 and Qwen Image 2512 at 0.63, have one thing in common: they are the only pipelines that use a LoRA to cut sampling down to 4 steps. MiniMax-H3 uses a turbo LoRA and Qwen Image 2512 uses the Lightning LoRA. So we ran a few experiments to find out whether the LoRA is to blame.
Why the LoRA pipelines diverge
Without the LoRA, the engines agree
First we removed the LoRA and ran both models the way they are meant to run without one: Qwen Image 2512 with 50 steps and CFG 4, and MiniMax-H3 with 40 steps. Everything else, including the prompt and seed, is the same as above.
Qwen Image 2512, no LoRA: SSIM 0.9806
MiniMax-H3 Video, no LoRA: SSIM 0.9000
Without the LoRA, Qwen Image 2512 lands next to Qwen Image 2.1, and MiniMax-H3 lands in the same range as the other video pipelines. The base models run the same in both engines.
One note on the Qwen run. Without the Lightning LoRA, Qwen Image 2512 is meant to run with the sigma schedule from its scheduler_config.json and with the CFG rescale from the reference diffusers pipeline. That rescale scales the guided prediction back to the length of the conditional prediction, for every latent patch. Nox implements both. ComfyUI’s stock nodes don’t offer the exact same combination, so for this experiment only, we gave ComfyUI the same sigmas through its ManualSigmas node and added a small custom node for the rescale.
Two ways to apply a LoRA
A LoRA adds a small low-rank update on top of a model’s weights. There are two ways to apply it:
- Merge. Add the update into the weights once, before sampling. This is what ComfyUI’s standard
LoraLoaderModelOnlynode does. With INT8 weights, ComfyUI dequantizes each adapted weight, adds the update, and quantizes it back to INT8 with a new scale and stochastic rounding. The merged weights are close to the original weights plus the LoRA, but every value picks up a new rounding error. - Bypass. Leave the weights untouched and compute the LoRA as a separate small matmul next to each layer, adding its result to the layer’s output. This is what Nox does. The INT8 base weights stay exactly as published and the LoRA runs in BF16. ComfyUI offers the same method in its
LoraLoaderBypassModelOnlynode.
Both are correct ways to apply a LoRA. Bypass doesn’t round the LoRA into INT8, so in principle it is the more exact of the two. The difference between them isn’t small: a merge doesn’t only round the update, it quantizes the whole weight again, and the Qwen Lightning LoRA touches every attention and MLP projection in all 60 transformer blocks. The merged model is effectively a second INT8 quantization of the original.
Measuring the divergence
If the LoRA method explained the whole gap, switching ComfyUI to bypass would close it. We ran both LoRA methods, with and without the attention swap from the table above:
| First output | Second output | What differs | Qwen Image 2512 | MiniMax-H3 |
|---|---|---|---|---|
| Nox, bypass | ComfyUI, merge | Engine and LoRA method (the benchmark) | 0.63 | 0.48 |
| Nox, bypass | ComfyUI, bypass | Engine only | 0.77 | 0.59 |
| ComfyUI, merge | ComfyUI, bypass | LoRA method only | 0.65 | 0.48 |
| ComfyUI, merge | ComfyUI, merge | Attention kernel only | 0.92 | 0.66 |
| ComfyUI, bypass | ComfyUI, bypass | Attention kernel only | 0.82 | 0.58 |
| ComfyUI, merge | ComfyUI, merge | Seed only (43 vs 44) | 0.47 | 0.40 |
Two things stand out:
- The LoRA method is the biggest single factor. ComfyUI with only the LoRA node swapped (merge vs bypass) disagrees with itself as much as it disagrees with Nox: 0.65 against 0.63 for Qwen Image 2512, and 0.48 against 0.48 for MiniMax-H3. Switching ComfyUI to bypass closes a large part of the gap, but not all of it.
- With the same LoRA method, Nox comes close to ComfyUI’s score against itself. With both engines using bypass, Nox scores 0.77 on Qwen Image 2512 and 0.59 on MiniMax-H3, against 0.82 and 0.58 for ComfyUI bypass with the attention swap.
Two causes
Neither engine applies the LoRA wrongly, but the gap wasn’t only noise either.
- The LoRA method. Merging quantizes every adapted weight into INT8 again and bypass doesn’t, so the two methods run measurably different weights.
- Sensitivity. MiniMax-H3 reacts to small numerical differences far more than the other pipelines: even the attention swap inside ComfyUI only scores 0.66. A likely reason is that it generates video and audio together: one sequence of tokens in a single transformer, with the audio on its own noise schedule. With the turbo LoRA at 4 steps the audio takes very large steps, and because the audio and video tokens attend to each other, that can also move the video.
Nox lands close to where ComfyUI lands against itself. The remaining gap in the benchmark table comes from merge vs bypass and, for MiniMax-H3, from how sensitive the model is. Neither output is the “correct” one. Both are equally valid renders of the same prompt, seed and model.
If you do run the benchmark and your numbers for the same GPU differ a lot from ours, we’d like to hear about it.