NOX ENGINE
High-performance inference engine for image and video
Nox is an inference engine for NVIDIA GPUs. It specializes in executing INT8 ConvRot models as fast as possible
3× faster on average than ComfyUI running the same INT8 ConvRot checkpoints in published warm-run benchmarks.PERFORMANCE
Measured image and video performance on NVIDIA GPUs.
Warm-run generation time across GPUs
Same pipeline · Lower is fasterSelect a GPU above to show its timings.
Warm-run generation time
Measured on an NVIDIA GeForce RTX 3090 · Lower is faster · seconds| Pipeline | ComfyUI | Nox | Speedup |
|---|---|---|---|
| Anima | 6.15s | 2.39s | 2.57× |
| FLUX.2 Klein 4B | 4.25s | 1.45s | 2.93× |
| FLUX.2 Klein 9B | 7.98s | 2.55s | 3.13× |
| Ideogram 4 | 16.56s | 8.17s | 2.03× |
| Krea2 | 22.92s | 7.92s | 2.89× |
| LTX 2.3 | 37.52s | 15.45s | 2.43× |
| LTX 2.5 | 36.22s | 14.98s | 2.42× |
| MiniMax H3 | 41.10s | 18.66s | 2.20× |
| Qwen Image 2512 | 9.49s | 4.00s | 2.37× |
| Qwen Image 2.1 | 42.73s | 13.19s | 3.24× |
| SDXL | 8.61s | 6.27s | 1.37× |
| Z-Image | 12.71s | 3.99s | 3.19× |
Both engines run the exact same INT8 ConvRot checkpoints for every model in this benchmark except SDXL, which both run in FP16.
Warm runs
Models are loaded by an initial generation. Subsequent runs use a new seed for a fresh result.
Comparison
Nox versus stock ComfyUI, both loading the exact same checkpoints. Time runs from request submission to completion, excluding output download. Speedup = ComfyUI time ÷ Nox time.
Pipeline settings and full results: Source report
Warm-run generation time
Measured on an NVIDIA GeForce RTX 4080 · Lower is faster · seconds| Pipeline | ComfyUI | Nox | Speedup |
|---|---|---|---|
| Anima | 4.55s | 1.53s | 2.97× |
| FLUX.2 Klein 4B | 3.65s | 0.95s | 3.84× |
| FLUX.2 Klein 9B | 6.78s | 1.65s | 4.11× |
| Ideogram 4 | 12.91s | 4.83s | 2.67× |
| Krea2 | 18.53s | 4.82s | 3.84× |
| LTX 2.3 | 29.30s | 11.17s | 2.62× |
| LTX 2.5 | 28.20s | 11.37s | 2.48× |
| MiniMax H3 | 34.25s | 11.51s | 2.98× |
| mossimage | 9.20s | 2.31s | 3.98× |
| Qwen Image 2512 | 9.11s | 2.51s | 3.63× |
| Qwen Image 2.1 | 33.91s | 8.13s | 4.17× |
| SDXL | 5.98s | 4.45s | 1.34× |
| Z-Image | 9.95s | 2.71s | 3.67× |
Both engines run the exact same INT8 ConvRot checkpoints for every model in this benchmark except SDXL, which both run in FP16.
Warm runs
Models are loaded by an initial generation. Subsequent runs use a new seed for a fresh result.
Comparison
Nox versus stock ComfyUI, both loading the exact same checkpoints. Time runs from request submission to completion, excluding output download. Speedup = ComfyUI time ÷ Nox time.
Pipeline settings and full results: Source report
Warm-run generation time
Measured on an NVIDIA GeForce RTX 5090 · Lower is faster · seconds| Pipeline | ComfyUI | Nox | Speedup |
|---|---|---|---|
| Anima | 3.60s | 1.05s | 3.43× |
| FLUX.2 Klein 4B | 2.44s | 0.72s | 3.39× |
| FLUX.2 Klein 9B | 3.58s | 1.07s | 3.35× |
| Ideogram 4 | 6.26s | 2.92s | 2.14× |
| Krea2 | 8.70s | 2.73s | 3.19× |
| LTX 2.3 | 19.96s | 6.42s | 3.11× |
| LTX 2.5 | 19.69s | 6.47s | 3.04× |
| MiniMax H3 | 30.63s | 5.89s | 5.20× |
| Qwen Image 2512 | 4.77s | 1.63s | 2.93× |
| Qwen Image 2.1 | 16.52s | 4.80s | 3.44× |
| SDXL | 9.07s | 2.27s | 4.00× |
| Z-Image | 5.85s | 1.61s | 3.63× |
Both engines run the exact same INT8 ConvRot checkpoints for every model in this benchmark except SDXL, which both run in FP16.
Warm runs
Models are loaded by an initial generation. Subsequent runs use a new seed for a fresh result.
Comparison
Nox versus stock ComfyUI, both loading the exact same checkpoints. Time runs from request submission to completion, excluding output download. Speedup = ComfyUI time ÷ Nox time.
Pipeline settings and full results: Source report
Warm-run generation time
Measured on an NVIDIA H100 80GB HBM3 · Lower is faster · seconds| Pipeline | ComfyUI | Nox | Speedup |
|---|---|---|---|
| Anima | 2.57s | 0.59s | 4.36× |
| FLUX.2 Klein 4B | 1.94s | 0.42s | 4.62× |
| FLUX.2 Klein 9B | 3.47s | 0.63s | 5.51× |
| Ideogram 4 | 7.33s | 1.77s | 4.14× |
| Krea2 | 10.20s | 2.02s | 5.05× |
| LTX 2.3 | 17.74s | 5.25s | 3.38× |
| LTX 2.5 | 18.09s | 4.99s | 3.63× |
| MiniMax H3 | 14.49s | 4.05s | 3.58× |
| Qwen Image 2512 | 4.47s | 1.12s | 3.99× |
| Qwen Image 2.1 | 18.18s | 3.00s | 6.06× |
| SDXL | 3.19s | 1.51s | 2.11× |
| Z-Image | 5.29s | 1.05s | 5.04× |
Both engines run the exact same INT8 ConvRot checkpoints for every model in this benchmark except SDXL, which both run in FP16.
Warm runs
Models are loaded by an initial generation. Subsequent runs use a new seed for a fresh result.
Comparison
Nox versus stock ComfyUI, both loading the exact same checkpoints. Time runs from request submission to completion, excluding output download. Speedup = ComfyUI time ÷ Nox time.
Pipeline settings and full results: Source report
NOX ENGINE
Built for image and video inference
Specialized INT8 execution
INT8 ConvRot is a form of quantization that uses 8-bit integers for model execution and targets near-BF16 quality. Nox is built to execute these quantized models as fast as possible on NVIDIA GPUs for image and video generation.
Plan first. Execute exactly.
Nox plans execution and GPU memory use before generation, then executes that plan exactly. Available VRAM and model offloading are accounted for in advance, keeping memory use predictable across the pipeline.
Supported image & video models
Image
- Anima
- FLUX.2 Klein 4B & 9B
- Ideogram 4
- Krea2
- Qwen Image 2.1
- Qwen Image 2512
- Qwen Image Edit 2511
- SDXL
- Z-Image
Video
- LTX 2.3
- LTX 2.5
- MiniMax H3
MADE WITH NOX
Every image below was generated with Nox using Krea2.
LUX WORKSPACE
Generate images and video, adjust prompts and LoRAs.
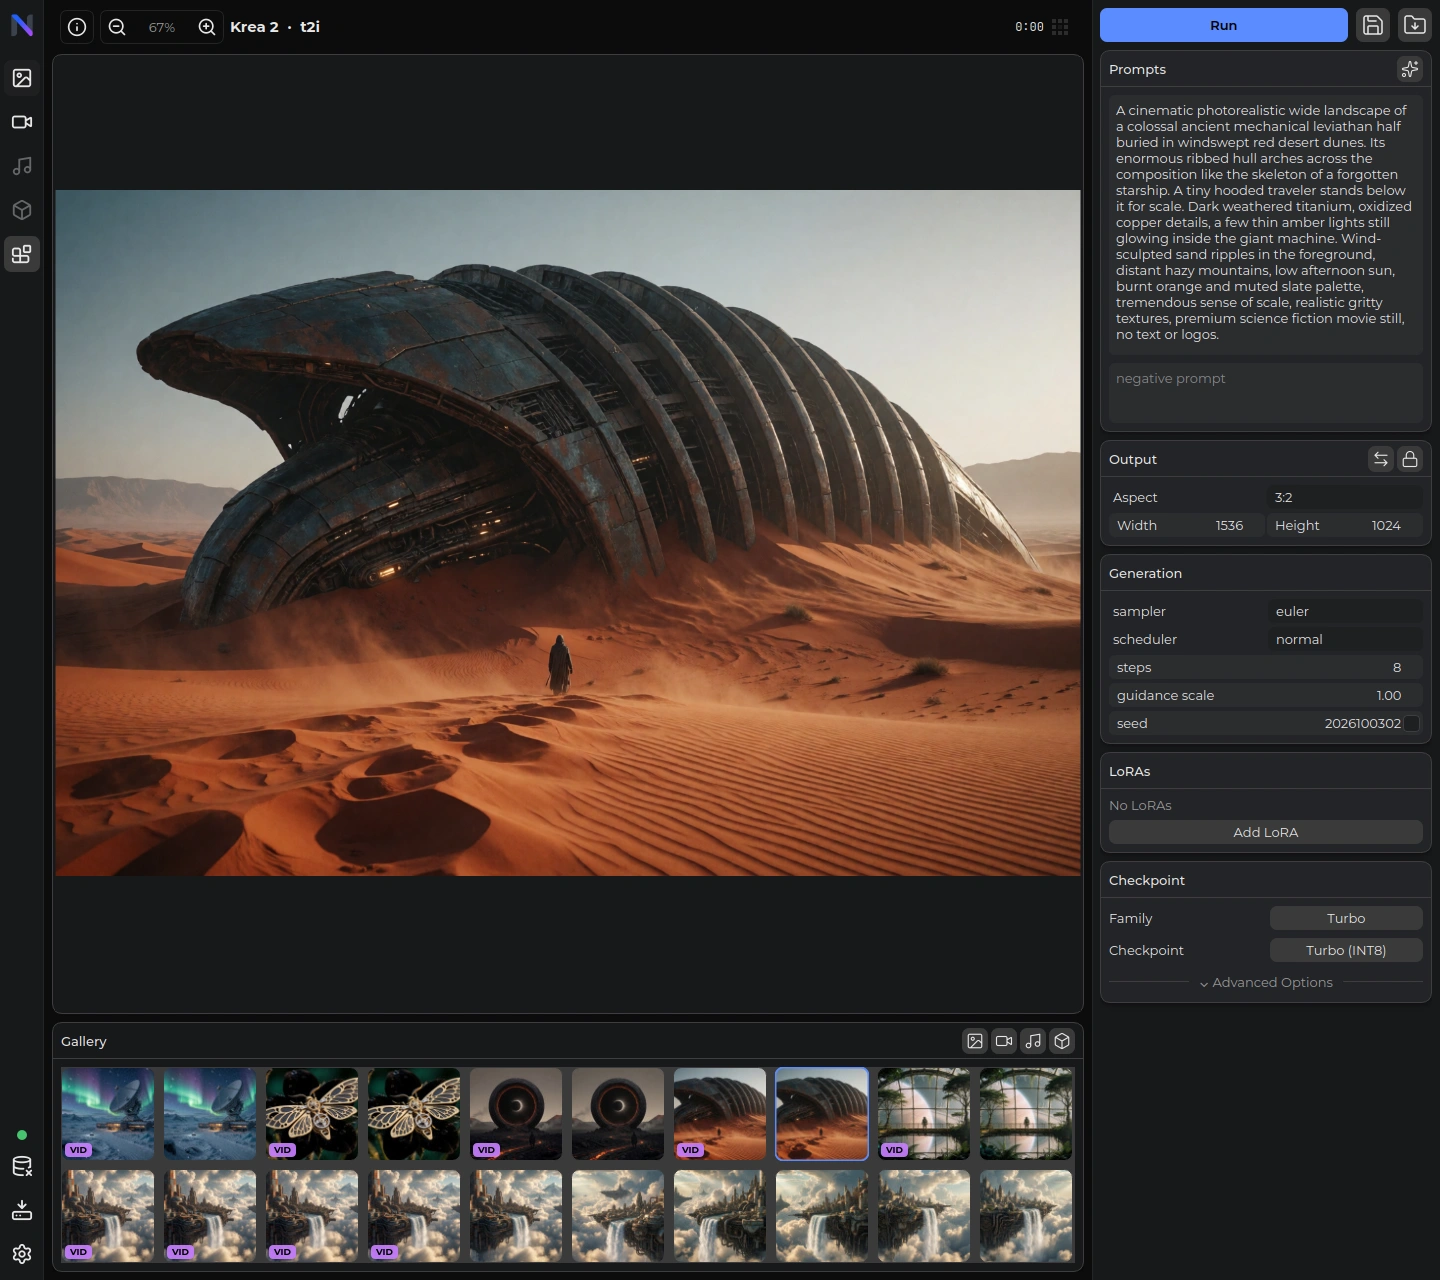
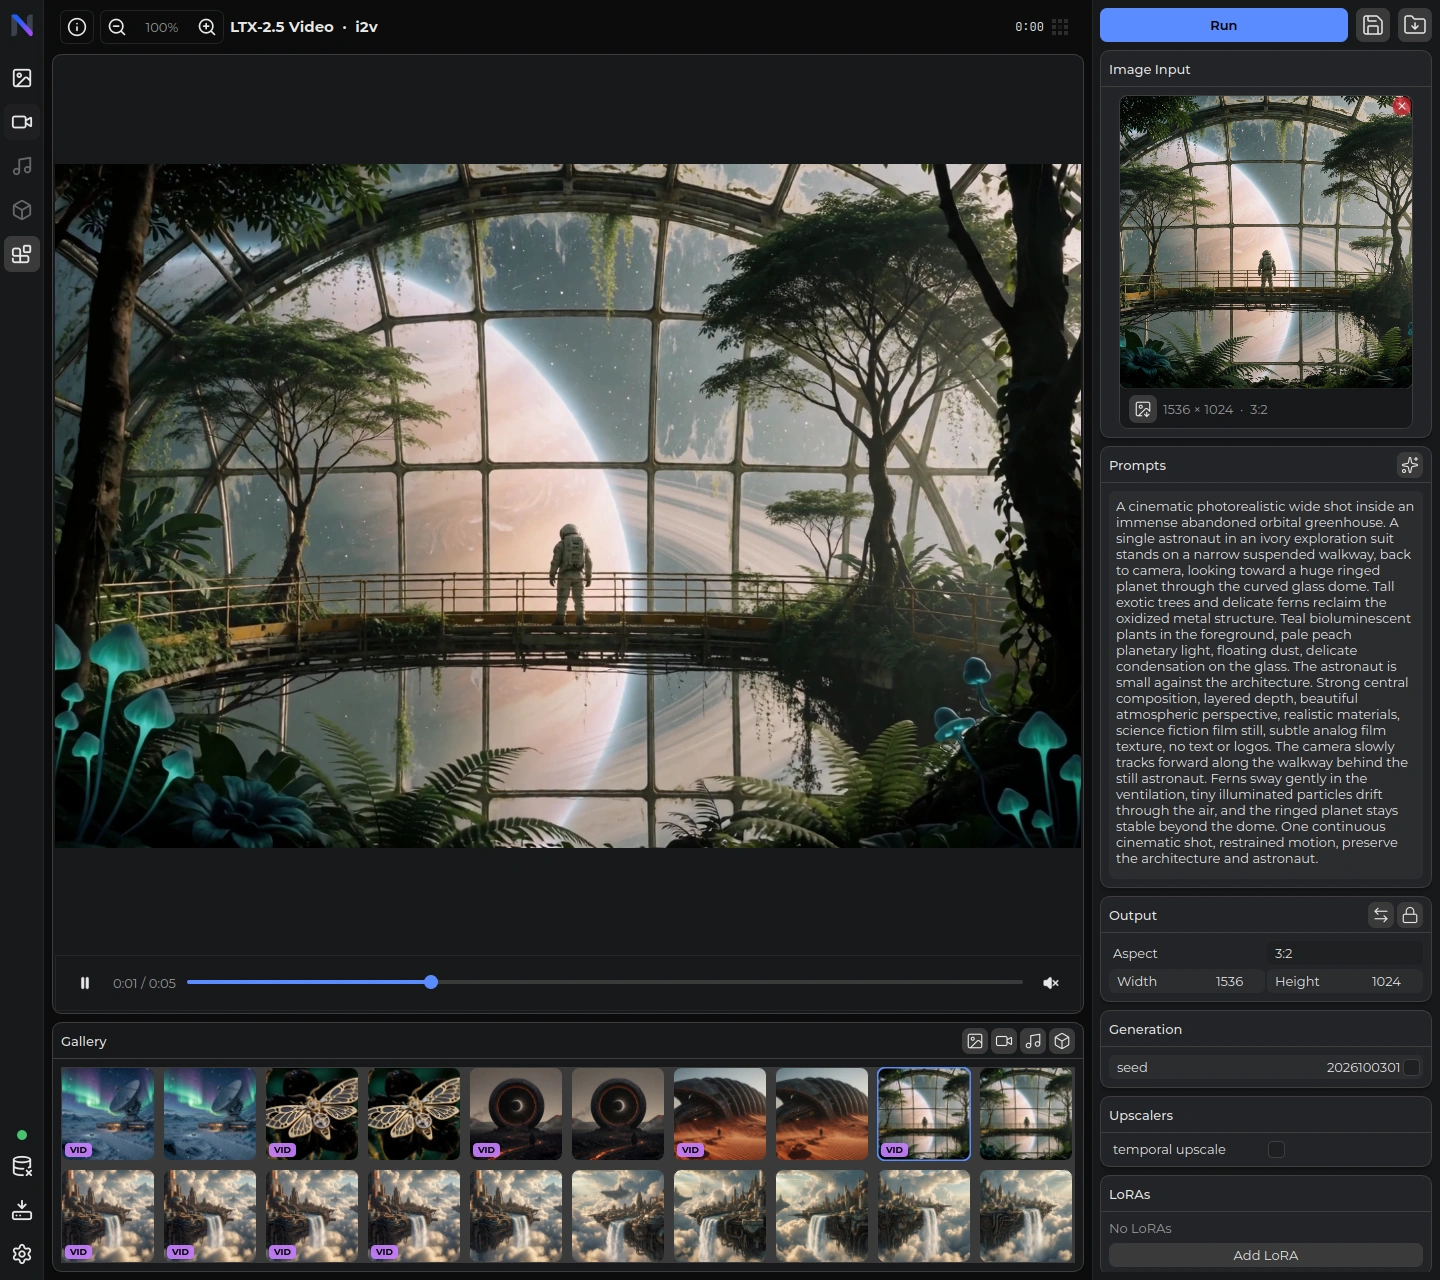
Lux desktop frontend · Nox inference engine
CONTACT
Interested in Nox for your application or workflow? Get in touch.